What LLM Tokens Really Cost (and How to Estimate Your Bill)
Tokens, context windows, input vs output pricing: how large language model costs add up, and how to estimate your monthly bill before it surprises you.
Computing···4 min read
What a token actually is
Large language models don't read characters or words. They read tokens. A token is a chunk of text, roughly ¾ of a word on average in English. A useful rule of thumb:
- ~4 characters ≈ 1 token
- ~750 words ≈ 1,000 tokens
- A dense page of text ≈ 500–800 tokens
Punctuation, code, and non-English text tokenize differently (often more tokens per character), so treat these as estimates, not guarantees.
Why your bill has two prices
Almost every API charges input tokens and output tokens at different rates, and output is usually several times more expensive. That matters because the two scale differently:
- Input grows with your prompt and everything you stuff into context (instructions, retrieved documents, chat history).
- Output grows with how much the model writes back.
Show the numbers
| Model | Input | Output |
|---|---|---|
| GPT-6.1 Sol | $2 | $10 |
| Claude Sonnet 5.5 | $2 | $10 |
| Gemini 3.1 Pro | $2 | $12 |
| Gemini 3.8 Flash | $0.75 | $3.75 |
| DeepSeek V4 Pro | $1.30 | $2.60 |
A chatbot that quotes long documents but answers briefly is input-heavy. A code generator or writing assistant is output-heavy. Knowing which you are tells you where to optimize.
The context window trap
The biggest surprise in most bills is conversation history. In a multi-turn chat, many implementations resend the entire prior conversation as input on every new message. So turn 20 might send 20 turns' worth of tokens, even though the user only typed one line.
Show the numbers
| Turn | Whole chat resent | Only the new turn |
|---|---|---|
| 1 | 200 | 200 |
| 2 | 600 | 400 |
| 3 | 1,200 | 600 |
| 4 | 2,000 | 800 |
| 5 | 3,000 | 1,000 |
| 6 | 4,200 | 1,200 |
| 7 | 5,600 | 1,400 |
| 8 | 7,200 | 1,600 |
| 9 | 9,000 | 1,800 |
| 10 | 11,000 | 2,000 |
| 11 | 13,200 | 2,200 |
| 12 | 15,600 | 2,400 |
| 13 | 18,200 | 2,600 |
| 14 | 21,000 | 2,800 |
| 15 | 24,000 | 3,000 |
| 16 | 27,200 | 3,200 |
| 17 | 30,600 | 3,400 |
| 18 | 34,200 | 3,600 |
| 19 | 38,000 | 3,800 |
| 20 | 42,000 | 4,000 |
Costs then grow roughly with the square of conversation length if you're not careful. Mitigations:
- Truncate or summarize old turns instead of resending them verbatim.
- Cache stable parts of the prompt where the provider supports it.
- Retrieve only the relevant snippets rather than dumping whole documents.
Estimating a monthly bill
The basic formula per request is:
cost = (input_tokens  × input_price_per_token)
     + (output_tokens × output_price_per_token)
Then multiply by requests per day and days per month. The parts people underestimate:
- System prompt + retrieved context: often larger than the user's actual question.
- Retries and tool calls: an agent that calls tools loops through the model multiple times per user turn.
- Growth: traffic rarely stays flat.
Rather than do this by hand, plug your numbers into the LLM token budget calculator to project a monthly cost.
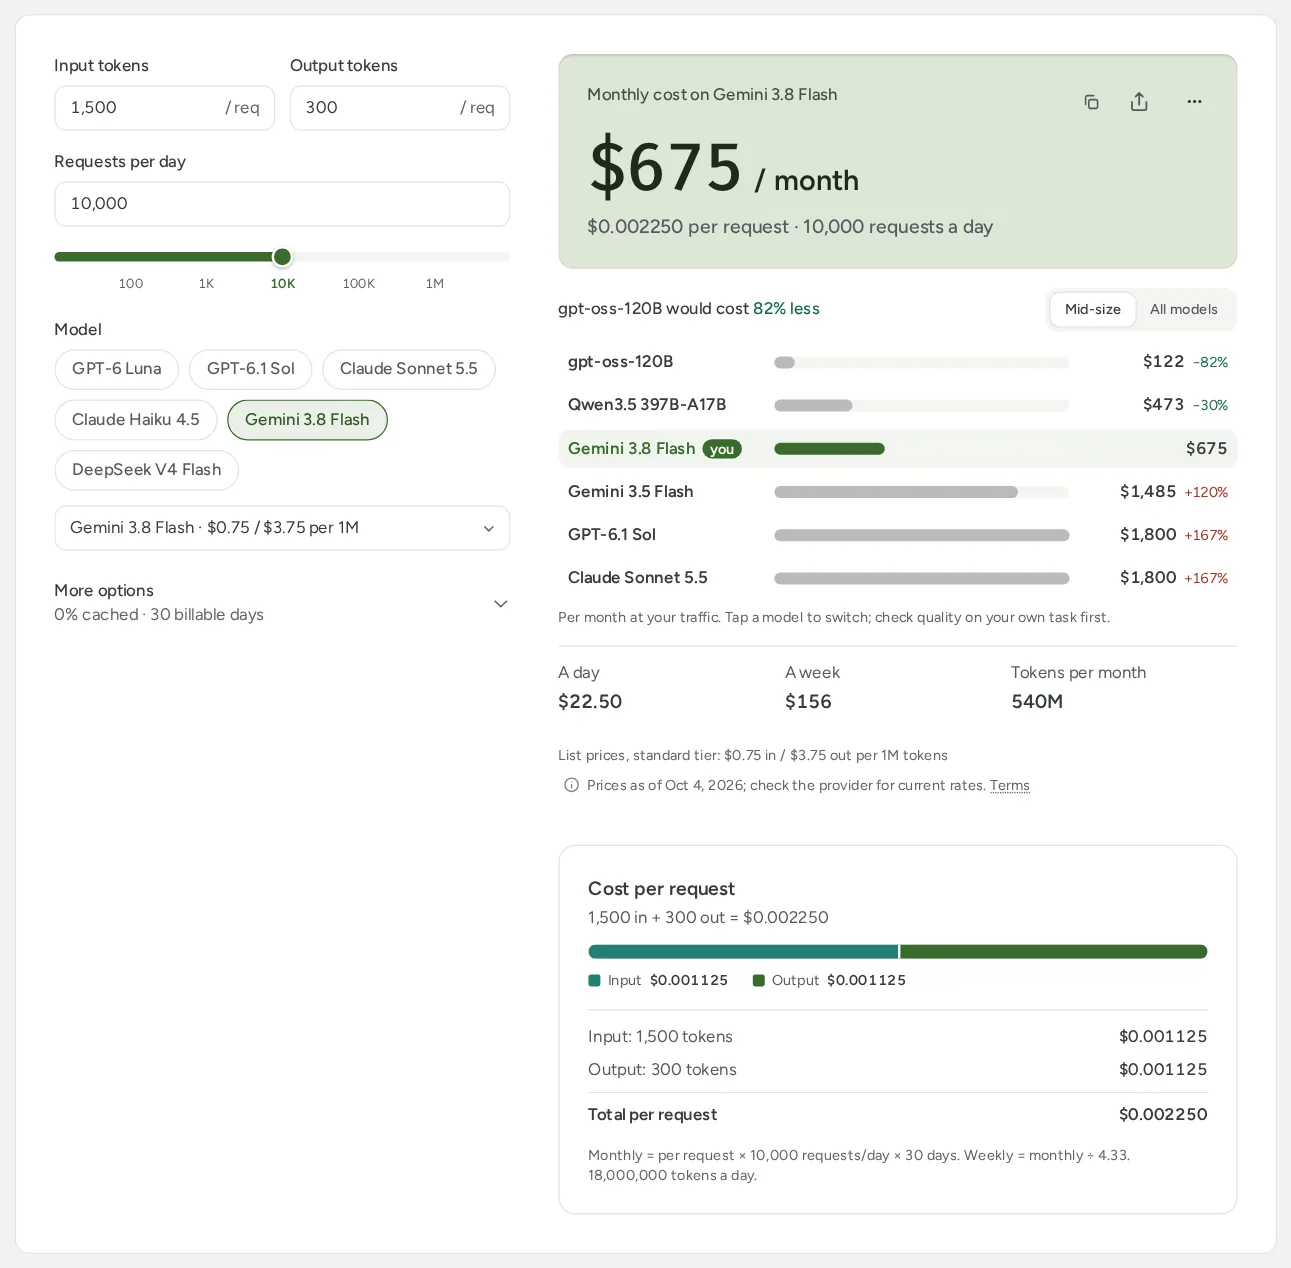
For example, a support bot that sends 1,500 input tokens and gets 300 back, 10,000 times a day for 30 days on Gemini 3.8 Flash: 450 million input tokens at $0.75 per million and 90 million output tokens at $3.75 per million are $337.50 each, so the output is a sixth of the tokens and half the bill.
API vs self-hosting
At low-to-moderate volume, a hosted API almost always wins on total cost of ownership: you pay only for what you use and skip GPUs, ops, and idle capacity. Self-hosting starts to make sense at high, steady volume, where fixed infrastructure amortizes across enough requests.
The crossover depends on your throughput, model size, and how well you'd keep the hardware busy. The self-hosted vs API calculator lets you compare the two for your specific load instead of guessing.
The short version
- Tokens ≈ ¾ of a word; budget both input and output, and output costs more.
- Conversation history and retrieved context are usually the hidden cost drivers.
- Estimate before you launch, then watch real usage. The first bill is where assumptions go to die.
Share this post
Keep reading
Computing· Nov 4, 2026· 15 min
What Is AGENTS.md? How to Write One Your Coding Agent Follows
AGENTS.md is a Markdown file of instructions for AI coding agents. Where it goes, which agents read it, how it differs from CLAUDE.md, and an example.Computing· Oct 7, 2026· 12 min· Updated Nov 2026
Chrome's Built-in AI (Gemini Nano): What It Can and Can't Do
Chrome now ships a small AI model that runs on your own computer. What it's good at, where it falls short, which APIs are ready, and when to use your own key.Computing· Oct 7, 2026· 11 min· Updated Nov 2026
Common JSON Errors and How to Fix Each One
Trailing commas, single quotes, comments, NaN, escaped strings and big numbers that change: why JSON rejects each one, and the fix that works.